

Immediate problem: why rental LED projects fail
Shows stop when panels flicker, seams misalign, or power racks trip at peak moments. These are not abstract risks; they come from predictable causes: connector wear, firmware divergence, and rushed onsite swaps. When you plan a led wall rental, expect tight turnaround and variable crews. That combination makes prevention the only reliable strategy.
Root causes engineers encounter most
Mechanical fatigue: cabinet latches and DVI/ethernet plugs wear faster than people assume. Thermal stress: stacked cabinets without adequate airflow develop color shifts and dead pixels. Software drift: mismatched firmware between batches produces synchronization errors. Logistics failures: missing spare modules or undocumented serial numbers delay repairs. Each failure mode has fixed diagnostics and repeatable fixes; treat them as problems to remove, not nuisances to manage.
Practical service checklist and common mistakes
Start with inventory control: label every panel and maintain a simple log of firmware versions and test patterns. Do a bench test for brightness, color balance, and heat soak before every load-in. Common mistakes: trusting visual checks alone; skipping firmware updates until the day of the event; over-relying on temporary fixes like tape or glue on connectors. Use multimeter and loopback tests to confirm power rails and data chains. Keep a minimal spare kit: two spare modules per 100 cabinets and a spare power supply per cluster reduces mean time to repair sharply.
Lifecycle triggers: when to repair, overhaul, or replace
Decide by measured metrics, not intuition. Replace modules when dead pixel rate exceeds contracted tolerance or when color calibration requires repeated corrections. Overhaul cabinets after five years of rental cycles or after repeated mechanical failures; swap internal fans and power caps proactively. Obsolescence is visible in parts availability—if you must custom-order a PSU with long lead times, plan replacement. Budget three lifecycle bands: tactical (on-site spares), strategic (scheduled overhauls), and capital (full fleet replacement). Each band has cost trade-offs; calculate using service hours per event and average downtime cost per hour.
EEAT and a real-world anchor
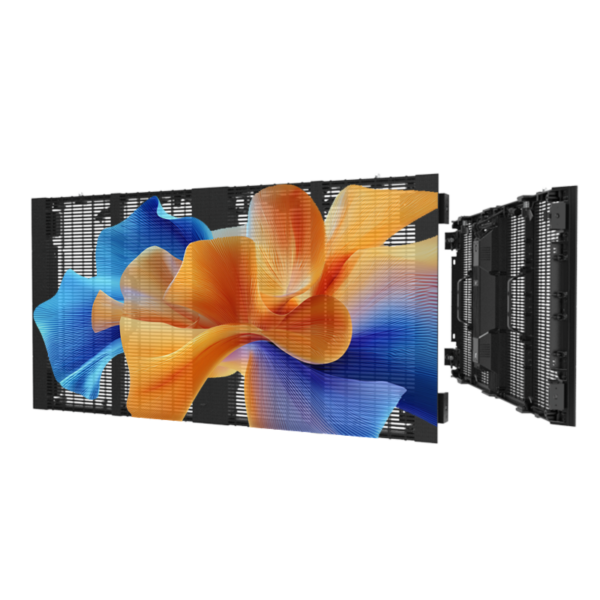
I have led maintenance teams on multi-city tours and audited rental fleets for broadcast clients; that practical record informs these priorities. Industry professionals discuss fleet reliability at major trade shows—at IBC Amsterdam, rental led board deployments and repair workflows are a recurring topic, reflecting the field’s standards and vendor commitments (rental led board). Use that public dialogue and published show reports to validate repair-cycle norms for contracts and SLAs.
Integrate maintenance into procurement and operations
Write serviceability into purchase orders: modular designs, documented firmware policies, and spare-part kits. Train two technicians per tour on your fleet specifics and require a pre-tour verification report. Avoid vendor-neutral assumptions; ask suppliers for clear serial-trace documentation and firmware change logs. When you schedule replacements, prioritize panels with recurring faults rather than those with one-off issues.
Final synthesis
Fix the predictable problems—connectors, thermal management, firmware, and spare logistics—and you remove the biggest single cause of show failures. The predictable path leads to measured maintenance cycles, clear inventory control, and vendor relationships that reflect real service needs, as evidenced at annual trade forums and in field audits; that is the practical value many teams find when they work with HDC.